
Research status — preliminary. This report describes an early result from the development of Skinki, not a peer-reviewed study. The real-data experiment covers 20 LongMemEval multi-session questions. That sample is too small for a publication-grade estimate, and the available artifacts do not support confidence intervals. These numbers are best read as a falsification signal rather than a general verdict on GraphRAG.
The graph behaved as designed. That was precisely why its failure to transfer deserved attention: the design fit the first test unusually well.
On a deterministic synthetic memory corpus, a typed relation retriever raised multi-hop recall@10 from 0.325 for BM25 to 0.800. The gain was large, reproducible, and protected by a regression gate. At that point, graph-structured retrieval looked like a credible approach to long-term agent memory.
I then moved the experiment to real dialogue. On a pooled subset of LongMemEval containing 20 multi-session questions and 9,697 dialogue turns, the graph variants scored 0.168 recall@10, below BM25 at 0.193. A dense retriever reached 0.291; a later coarse-to-fine search reached 0.438. The synthetic advantage was absent, and the graph also scored below the baseline in this small experiment.
This note reconstructs that reversal. It follows the tests in the order I ran them, then asks which differences between the two regimes could account for the result and which conclusions the evidence does not support.
The question
Long-term conversational memory poses a familiar retrieval problem. A question may depend on two statements separated by weeks of interaction:
- Anna introduced me to Marcus at a meetup.
- The person I met at the meetup recommended Dune.
Answering requires a join. Lexical retrieval may return either the introduction or the recommendation without connecting them. A graph supplies an appealing representation: people and venues become nodes, introductions and recommendations become typed edges, and traversal recovers the evidence chain.
That intuition leads to a deliberately narrow research question:
Does a typed relation graph improve the retrieval of multi-session evidence in long-term dialogue, or can its apparent advantage be an artifact of the benchmark and extractor that define the graph?
The outcome here is retrieval, not final answer quality from a reader LLM. Nor does the experiment evaluate graph memory as a provenance or maintenance substrate. Graphs may remain useful for either purpose even when they are poor rankers.
What was measured
For a question $q$, let $G_q$ be its gold evidence turns and $T_{10}(q)$ the first ten retrieved turns. The reported metric is macro-averaged evidence recall:
$$ \mathrm{Recall@10} = \frac{1}{|Q|} \sum_{q \in Q} \frac{|T_{10}(q) \cap G_q|}{|G_q|}. $$
Macro-averaging matters because a multi-session question may require several evidence turns. Recovering one supporting statement is not equivalent to recovering the evidence set.
I did not begin with a single benchmark run. The retrieval design moved through four tests, each prompted by a limitation exposed in the preceding one.
Round 1: reachability without ranking
The first graph connected entries through co-mentioned people and venues, then fused its candidates with BM25. On the synthetic V2 corpus—seed 42, five simulated years, approximately 11,500 entries—it tied BM25 at 0.325 multi-hop recall@10. The graph walk alone scored 0.175.
That result separated two properties I had initially treated together. Co-occurrence made many entries reachable, but a path was not a relevance score. Popular people and repeated venues flooded the candidate set; once noisy graph candidates entered fusion, they could displace useful lexical hits.
Round 2: the typed-relation gain
I next replaced generic co-mention with explicit relations. One edge represented an introduction, $P \xrightarrow{\text{introduced at }V} Q$; another represented a recommendation, $Q \xrightarrow{\text{recommended}} B$. For coreferential cases, the retriever could bridge through a venue and favor recommendations close in time to the introduction. Graph expansion ran only when a question contained introduction or recommendation cues, leaving ordinary single-hop queries on the BM25 path.
This version scored 0.800 recall@10, compared with 0.325 for BM25, and 0.900 versus 0.650 on the repository’s answer-in-top-10 proxy. At a larger synthetic scale of approximately 29,600 entries, the absolute scores fell, but the relative retrieval advantage remained: 0.422 versus 0.172.
The predefined synthetic gate passed. Yet the success came with an important coupling. The system and generator shared a vocabulary and a causal grammar: a small family of introduction and recommendation templates generated the corpus, while the retriever searched for a corresponding family of cues. It also built a gazetteer from the synthetic ground-truth entity names. That coupling does not invalidate the experiment, but it narrows the scope of the result.
Round 3: the oracle warning
Before paying for live extraction, I replayed a ground-truth oracle through the same artifact interface intended for an LLM. The oracle tier changed synthetic multi-hop recall by −0.125 at the default scale and +0.031 at the larger scale. At first, this was surprising.
The oracle resolved ambiguous recommendations to person names. Reused names then created new cross-chain collisions, whereas the deterministic venue-and-time bridge had already avoided some of them. Better extraction did not necessarily produce better ranking. In retrospect, this was an early warning: graph quality, entity quality, and retrieval quality were not interchangeable quantities.
Round 4: real dialogue
For the real-text campaign, I used two public conversational-memory benchmarks. LoCoMo contains long conversations spanning as many as 35 sessions. On the evaluated sample, BM25 already reached 0.784 recall@10 on category-2 multi-hop questions. With little unmet retrieval gap for the graph to close, it underperformed BM25 across the tested categories.
LongMemEval offered the more relevant stress test because its multi-session questions explicitly require evidence synthesis across sessions. I pooled every turn from 20 scoreable multi-session instances into one 9,697-entry search space and evaluated all retrievers at $k=10$.
| Retriever | Recall@10 | Answer@10 | nDCG@10 |
|---|---|---|---|
| BM25 | 0.193 | 0.450 | 0.154 |
| Co-mention graph + BM25 | 0.168 | 0.450 | 0.112 |
| Typed-fact graph + BM25 | 0.168 | 0.450 | 0.109 |
| EmbeddingGemma, 256 dimensions | 0.291 | 0.450 | 0.187 |
Both graph variants were 0.025 below BM25. Per-instance evaluation pointed in the same direction—0.360 and 0.363 for the two graph variants versus 0.372 for BM25—but the small sample produced an estimated uncertainty much larger than the observed difference. The defensible interpretation is therefore narrow: the synthetic gain did not reproduce, and this sample provided no evidence that the graph improved retrieval.
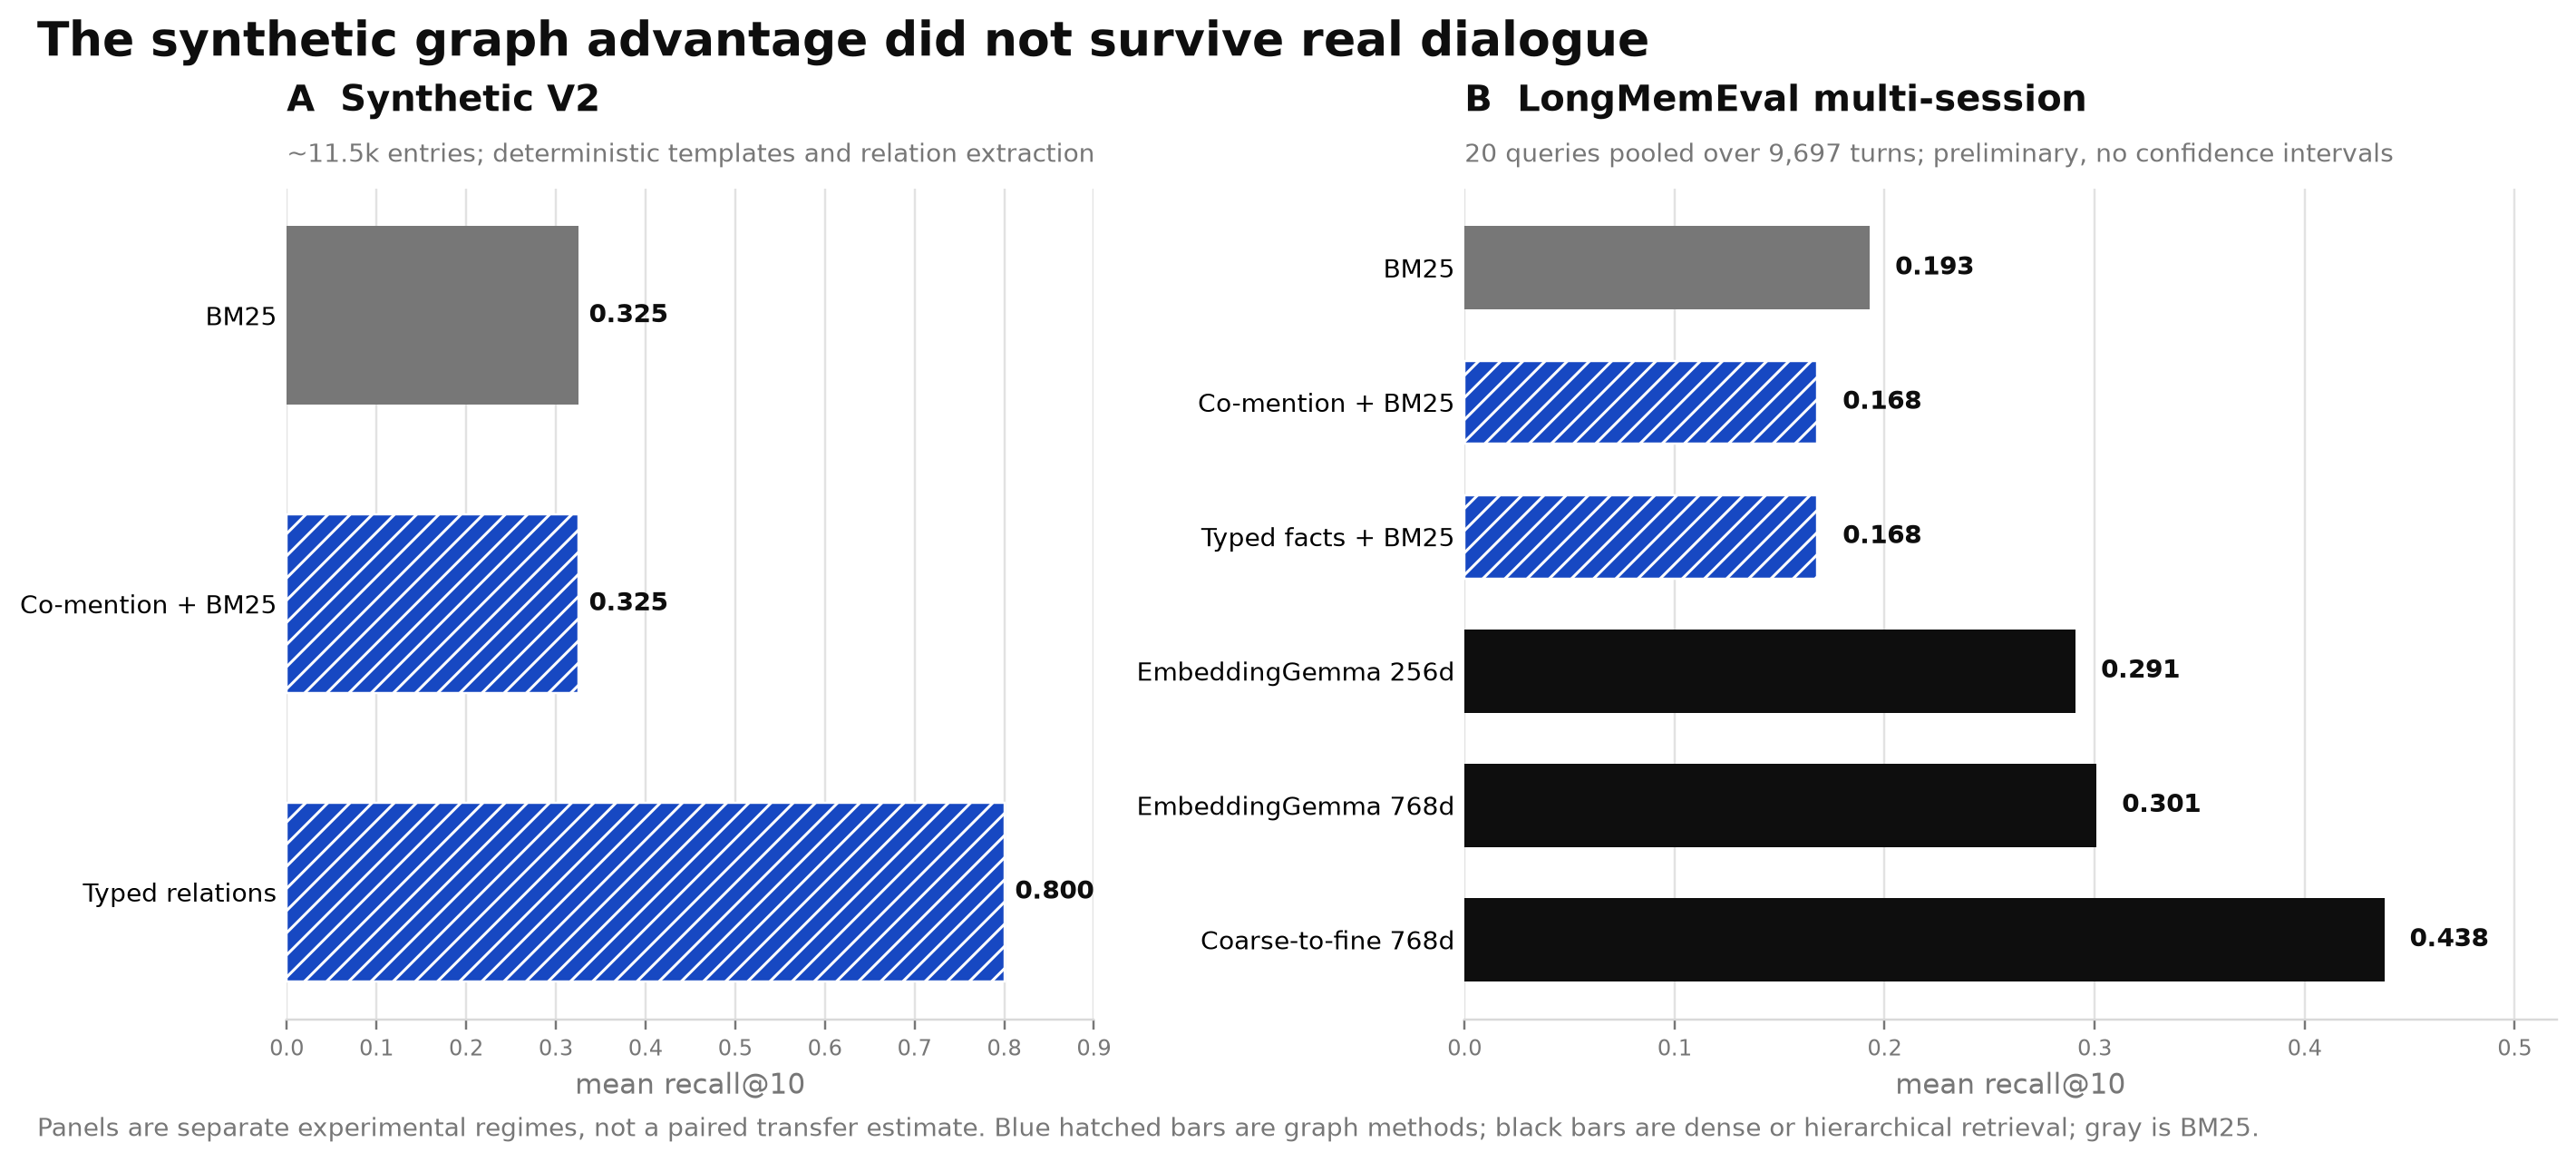
Figure 1. Mean recall@10 in two separate experimental regimes. Blue hatched bars denote graph methods; black bars denote dense or hierarchical retrieval; gray denotes BM25. Panel A uses the deterministic synthetic V2 corpus. Panel B uses a preliminary pooled LongMemEval subset. The panels are not a controlled domain-transfer estimate: corpus construction, extraction, query count, and parts of the retrieval pipeline differ. No uncertainty intervals are available for Panel B.
Why the result changed
The experiments do not identify a controlled causal explanation. They do, however, expose several points at which the synthetic task and real dialogue place different demands on a retriever. I treat these as diagnostics to test, not as established causes of failure.
A schema that already knew the task
In the synthetic corpus, the target chains were generated from a constrained set of introduction–recommendation templates. The deterministic retriever encoded the same relations and cues. The benchmark could therefore test whether the implementation recovered planted joins amid distractors, but it could not measure the cost of discovering an appropriate relation schema from unconstrained language.
In conversation, that cost appears as paraphrase, omitted arguments, aliases, speaker references, and coreference across turns. In many such cases, a usable edge must be inferred from evidence distributed across turns rather than read directly from a single utterance. The synthetic result demonstrated correctness at a known interface. Real dialogue first required the system to infer that interface.
Reachability was never the same as ranking
The first synthetic round had already shown this distinction, and the real-text result made it harder to ignore. Edges increased the amount of reachable evidence together with the amount of irrelevant material. The conversational graphs examined here contained hubs—speakers, recurring locations, common activities, and entities discussed across months. An erroneous or broad edge can pull an entire neighborhood into the candidate set.
Reciprocal-rank fusion cannot recover information that has already been lost when noisy graph candidates displace the lexical ranking. Graph construction is not a free preprocessing step; it is a second retrieval model with its own error distribution.
Extraction errors changed the search space
The real-dialogue run surfaced speaker hubs, alias mismatches, unresolved coreference, and noisy typed facts. Filtering conversational hubs helped only marginally in the LoCoMo probe. Prefix-based entity merging could combine names that should remain separate while missing variants that referred to the same person.
These are not merely passage-scoring errors. In a flat text index, a mistaken entity interpretation changes a score. In a graph, it may create a false path and redistribute relevance across many passages. An extractor can therefore look acceptable in isolation while its errors still make the resulting graph a worse retrieval structure.
The stronger structure was hierarchical
After the graph result, I kept dense embeddings and changed where the system searched. The follow-up averaged turn embeddings into one vector per LongMemEval instance, selected the three most relevant instances, and searched individual turns only inside them.
On the same 20-instance pool, full-dimensional EmbeddingGemma scored 0.301 recall@10. Coarse-to-fine retrieval reached 0.438, a 46% relative improvement, while a term-frequency query-expansion experiment collapsed to 0.017. This does not establish coarse-to-fine retrieval as a general solution. LongMemEval itself reports that session decomposition and fact-level representations can improve multi-session reasoning. The local result supports a smaller inference: for this workload, a useful inductive bias concerned where in the conversation to search more than which entities to traverse.
Taken together, these observations suggest a specific follow-up rather than a verdict on graphs. The representation, extractor, and ranker need to be varied independently; otherwise a benchmark-aligned schema can conceal extraction cost, while an extraction failure can be misread as evidence against the representation.
How this relates to GraphRAG research
“GraphRAG” names a family of methods, not a single algorithm. The Skinki retriever is not a reproduction of Microsoft GraphRAG, HippoRAG, or LightRAG.
HippoRAG extracts an open knowledge graph and uses Personalized PageRank to retrieve on MuSiQue, 2WikiMultiHopQA, and HotpotQA. Its reported gains show that graph structure can work when the benchmark, graph construction, and traversal method align with multi-hop document QA. LightRAG combines graph and vector representations with low- and high-level retrieval. Other GraphRAG systems address global summarization rather than turn-level evidence recall.
The present experiment occupies a different regime: long, personal, temporally evolving dialogue; a small local extractor; and evidence-turn recall inside an agent-memory workload. This distinction matters because the result concerns the transfer of one retrieval design, not the viability of the wider GraphRAG family.
Recent work sharpens the point. AgentIR evaluates all 500 LongMemEval questions and 1,982 LoCoMo questions and reports workload-dependent retrieval choices: hybrid retrieval helps LongMemEval, whereas BM25 is the strongest single system on LoCoMo. Its scale and statistical treatment are far beyond this note. Still, its conclusion is compatible with the failure observed here—additional structure does not by itself guarantee a universal advantage.
What can be concluded
The evidence supports a limited sequence of claims. A typed relation graph produced a large, deterministic retrieval gain on a synthetic corpus whose planted causal structure matched the retriever’s schema. That gain did not appear in the small real-dialogue evaluations performed here. Within the pooled LongMemEval subset, dense retrieval and session-level coarse-to-fine search were stronger than the tested graph variants. The practical conclusion is correspondingly narrow: synthetic multi-hop success was insufficient evidence for adopting this graph retriever in conversational memory.
Nothing in the experiment establishes that GraphRAG is ineffective, that BM25 is generally superior, that coarse-to-fine retrieval is state of the art, or that the observed differences will persist on the full benchmarks. Those stronger propositions require evidence this study did not collect.
Limitations
The main pooled result contains 20 questions, too few for a precise effect estimate or subgroup analysis, and the publication bundle lacks the per-query artifacts required for paired bootstrap confidence intervals. LoCoMo coverage is narrower still: the recorded probe used one conversation sample rather than the complete benchmark. The apparent direction of an effect should not be mistaken for a reliable estimate of its size.
Transfer between the two regimes was also uncontrolled. The synthetic retriever relied on deterministic cues and a ground-truth-derived gazetteer; the real system used LLM-extracted entities and facts. Language distribution and extractor therefore changed together. Extractor provenance adds another ambiguity: the Stage-3 specification names Qwen-2.5-3B for typed-fact extraction, while the final LongMemEval commit records Qwen2.5-0.5B served through llama.cpp. I consequently describe the component only as a local Qwen 2.5 extractor and do not attribute the outcome to model scale.
Recall is not end-to-end utility. Equal answer-in-top-10 scores already show that evidence-retrieval metrics and answer availability can diverge, yet no reader LLM was evaluated under a fixed context budget. Reproduction is also incomplete: the public repository contains the harness and measurement record, but excludes the large LongMemEval extraction and embedding dumps.
Finally, development history is not peer review. Commit-time gates reduce the temptation to hide failed hypotheses; they do not substitute for independent reproduction. These limitations define the result rather than merely qualifying it.
The experiment that should come next
A publication-grade follow-up should begin by fixing its experimental contract. I would evaluate the complete LongMemEval multi-session split and the full LoCoMo QA set, storing per-query rankings, extraction artifacts, model hashes, prompts, and environment metadata in a replayable release. BM25, dense retrieval, RRF, session decomposition, coarse-to-fine retrieval, and at least one PPR-style graph baseline should then run against the same index and query set.
The decisive comparison is between an oracle graph and an extracted graph. Their difference measures extraction loss; the gap between the oracle graph and text baselines measures the value of the representation itself. Edge types, hub filtering, entity resolution, temporal weighting, and fusion should be ablated independently rather than introduced as a package.
Evaluation should report paired bootstrap intervals and effect sizes by question type, followed by an end-to-end reader study using the same model and prompt-token budget for every retriever. For that follow-up, the central quantity is a paired transfer effect rather than two isolated leaderboard numbers:
$$ \Delta_{\mathrm{graph}}(D) = R@10_{\mathrm{graph}}(D) - R@10_{\mathrm{baseline}}(D), $$
followed by the change in that effect between synthetic and real regimes. This contract would distinguish a small true benefit from noise, extraction failure, or benchmark coupling.
A failed transfer is still a result
Stopping when the synthetic score rose from 0.325 to 0.800 would have produced a cleaner story. Continuing the test produced the more useful one.
The result does not show that graphs are useless. It shows that a graph retriever is a hypothesis about the structure of relevance. Synthetic data may encode that hypothesis in its generator; real dialogue requires the system to infer the structure, tolerate extraction noise, control hubs, and still rank the right evidence above thousands of plausible neighbors.
The synthetic win was real within its test. Its failure to travel is the result worth carrying forward.
References
- Di Wu, Hongwei Wang, Wenhao Yu, Yuwei Zhang, Kai-Wei Chang, and Dong Yu. “LongMemEval: Benchmarking Chat Assistants on Long-Term Interactive Memory.” ICLR 2025. arXiv:2410.10813.
- Adyasha Maharana, Dong-Ho Lee, Sergey Tulyakov, Mohit Bansal, Francesco Barbieri, and Yuwei Fang. “Evaluating Very Long-Term Conversational Memory of LLM Agents.” 2024. arXiv:2402.17753.
- Bernal Jiménez Gutiérrez, Yiheng Shu, Yu Gu, Michihiro Yasunaga, and Yu Su. “HippoRAG: Neurobiologically Inspired Long-Term Memory for Large Language Models.” NeurIPS 2024. arXiv:2405.14831.
- Zirui Guo, Lianghao Xia, Yanhua Yu, Tu Ao, and Chao Huang. “LightRAG: Simple and Fast Retrieval-Augmented Generation.” 2024. arXiv:2410.05779.
- Haoyu Han et al. “Retrieval-Augmented Generation with Graphs (GraphRAG).” 2025. arXiv:2501.00309.
- Aojie Yuan, Haiyue Zhang, and Shahin Nazarian. “AgentIR: A Workload-Adaptive Cascade Retrieval Substrate for Long-Term Conversational Memory.” 2026. arXiv:2605.25092.
Reproducibility note
I prepared the article against Skinki commit 8a36399. Synthetic results are recorded in the Stage-3 gate and measurement log; real-text results are recorded in commits be28dc1, 27ffedd, f8288bf, and 26b15ab. The plotting data and script accompanying this article are a transcription of those records, not newly generated benchmark output. The missing raw real-text artifacts are the reason this note presents a preliminary falsification signal rather than a statistical claim.